Nvidia ties AI factory economics to tokens and power efficiency
AI factory economics increasingly hinge on inference revenue, low-latency workloads and power efficiency across Nvidia and CoreWeave systems.
Via SiliconANGLE
Nvidia ties AI factory economics to tokens and power efficiency
AI factory economics increasingly depend on more than access to high-performance graphics processing units. As agentic systems draw on multiple models, databases and tools, the entire data center must work as one computing system.
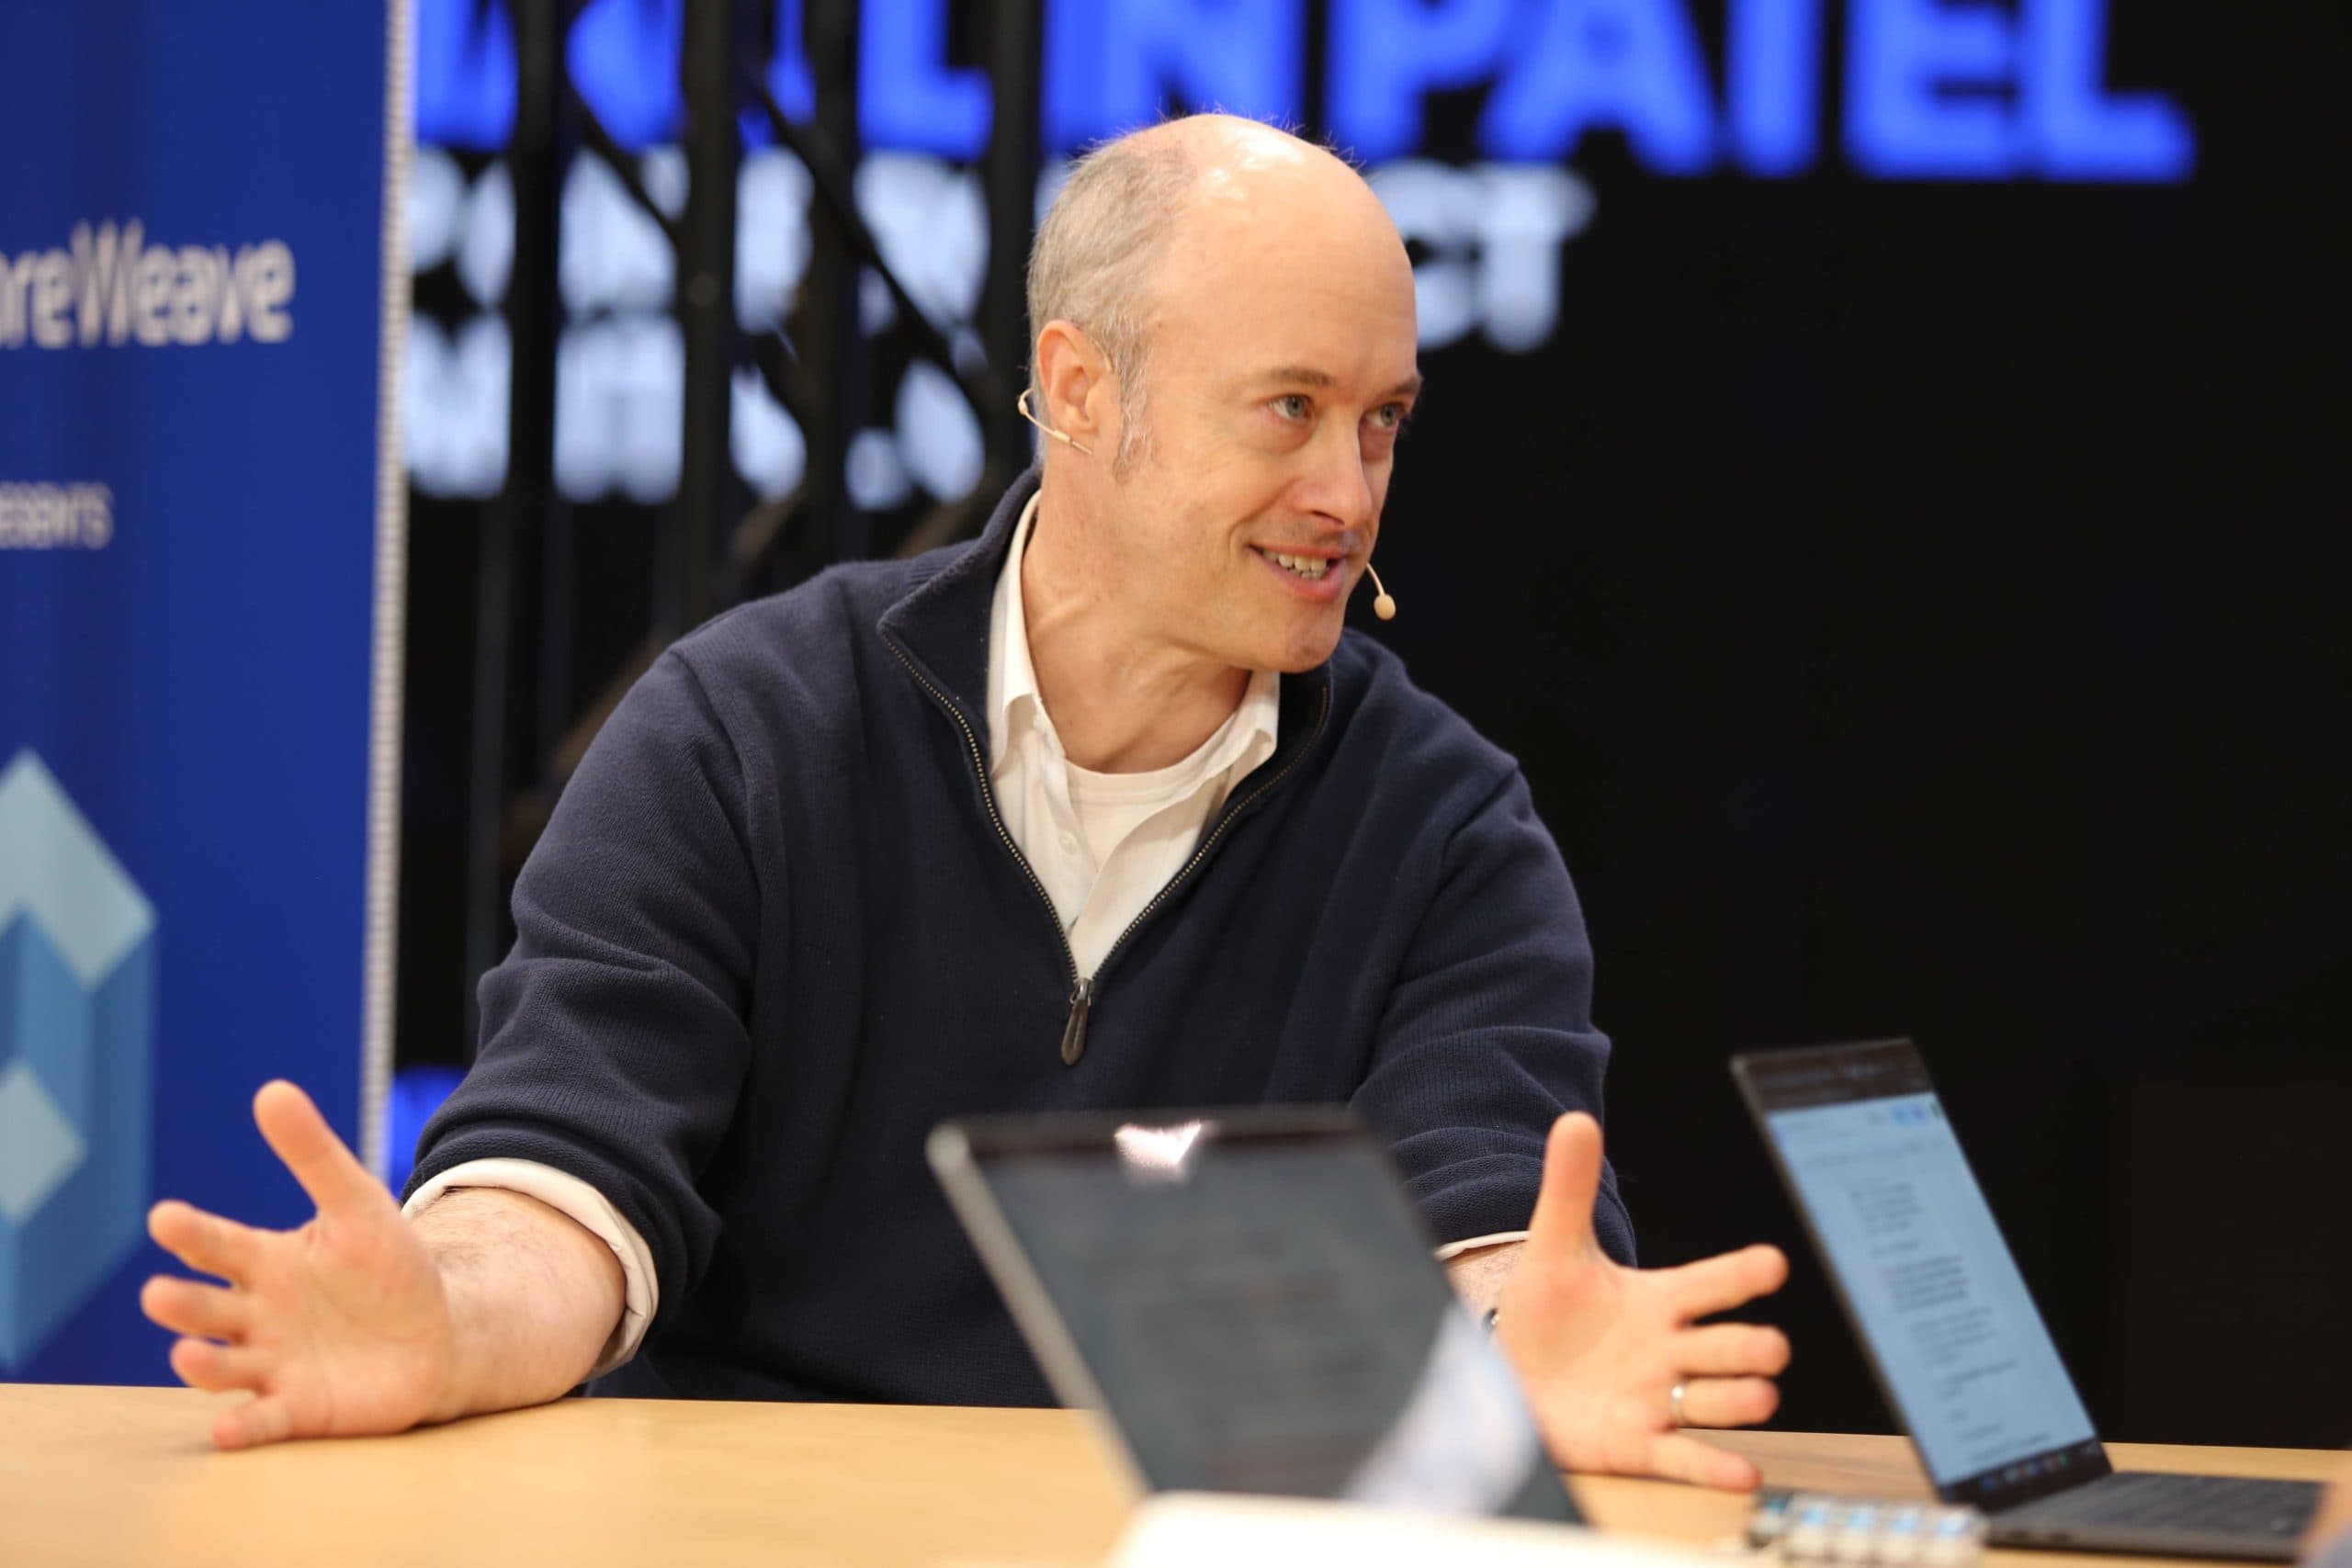
That transition is shifting attention from individual chips to the infrastructure that turns computing capacity into useful intelligence. Networking, storage, processors and software must operate together at scale while increasing the output generated from every unit of power, according to Ian Buck (pictured), vice president and general manager of hyperscale and HPC at Nvidia Corp.
“Instead of cars or devices or PCs, it’s tokens,” he said. “These assets are not IT; they’re not cost. They’re actually appreciating, revenue-generating, fungible, durable, productive parts of an economy.”
Buck spoke with theCUBE Research’s Dave Vellante and John Furrier at the Fully Connected event, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed inference, system-level design and the changing economics of AI infrastructure. (* Disclosure below.)
Inference reshapes AI factory economics
An AI factory’s commercial output comes from inference, in which deployed models process requests and produce tokens. Yet inference does not replace training, because organizations continually update deployed models as data and market conditions change, according to Buck.
“It’s not just fire and forget on all these services,” he said. “As companies are using these models, they’re refining them, they’re aligning them, they’re adding more data to them. Having them up to date and aware — that actually is a little bit of training. We’re seeing the work in reinforcement learning and online alignment.”
Low latency creates another economic tier for workloads in which faster reasoning has greater value. Nvidia’s Groq 3 LPX inference accelerator works with its Vera Rubin platform to increase per-user token rates for time-sensitive workloads.
“If there’s value in those tokens to have the fastest possible thinking, LPX can be boosted on top of Vera Rubin to make that possible,” Buck said. “We’re seeing a lot of interest in areas like fintech and other areas where things are happening in real time.”
Power makes efficiency a system-level priority
Power capacity ultimately limits how much computing infrastructure a data center can deploy. That constraint makes tokens per watt a central measure of AI factory economics and puts pressure on vendors to improve performance with each hardware generation.
“Data centers have a natural cap, and that cap is actually their power,” Buck said. “With every generation of GPU, we make sure that our tokens per watt is upwards of 10 times more efficient. In fact, we saw that with Blackwell — we got, in the end, a 30x improvement in tokens per watt.”
The shift also changes the scale at which systems must be designed and operated. CoreWeave allows customers to choose configurations or use higher-level inference services that optimize the balance between throughput and token speed, according to Buck.
“CoreWeave can do that for customers,” he said. “They don’t have to feel overwhelmed by all the choices. That’s where our partner ecosystem is so important.”
Here’s the complete video interview, part of SiliconANGLE’s and theCUBE’s coverage of the Fully Connected event:
(* Disclosure: TheCUBE is a paid media partner for the Fully Connected event. Neither CoreWeave, the sponsor of theCUBE’s coverage, nor other sponsors have editorial control over the content on theCUBE or SiliconANGLE.)
Photo: SiliconANGLE
A message from John Furrier, co-founder of SiliconANGLE:
Support our mission to keep content open and free by engaging with theCUBE community. Join theCUBE’s Alumni Trust Network, where technology leaders connect, share intelligence and create opportunities.
15M+ viewers of theCUBE videos, powering conversations across AI, cloud, cybersecurity and more
11.4k+ theCUBE alumni — Connect with more than 11,400 tech and business leaders shaping the future through a unique trusted-based network
SiliconANGLE Media is a recognized leader in digital media innovation, uniting breakthrough technology, strategic insights and real-time audience engagement. As the parent company of SiliconANGLE, theCUBE Network, theCUBE Research, CUBE365, theCUBE AI and theCUBE SuperStudios — with flagship locations in Silicon Valley and the New York Stock Exchange — SiliconANGLE Media operates at the intersection of media, technology and AI.
Founded by tech visionaries John Furrier and Dave Vellante, SiliconANGLE Media has built a dynamic ecosystem of industry-leading digital media brands that reach 15+ million elite tech professionals. Our new proprietary theCUBE AI Video Cloud is breaking ground in audience interaction, leveraging theCUBEai.com neural network to help technology companies make data-driven decisions and stay at the forefront of industry conversations.
Courtesy
This story was originally published by SiliconANGLE. All rights belong to the original publisher.
Read the original on siliconangle.com ↗