
Cerebras says agentic AI needs faster inference, cites 10-15x speed advantage
Cerebras Systems Inc., a provider of AI-optimized processors, recently underscored the importance of inference speed in powering agentic workflows. Speaking at the AI Data Pipeline Forum, the company reiterated its claim that its Wafer-Scale Engine outperforms rivals by 10 to 15 times, a message that aligns with its $5.5 billion IPO earlier this year.

Editor, Lazyfounder
30 SEC SUMMARY
- Cerebras Systems Inc., a chipmaker specializing in AI processors, highlighted the critical role of inference speed in agentic workflows during a recent industry forum.
- The company, which went public in May 2026 with a $5.5 billion IPO, claims its Wafer-Scale Engine delivers 10 to 15 times faster inference than competing platforms.
- Cerebras emphasized that agentic workflows require rapid, coordinated processing across multiple AI agents, shifting enterprise focus toward maximizing value per token.
- The company’s hardware is designed to address the demand for high-speed, memory-proximate compute, a key requirement for AI applications.
TABLE OF CONTENTS
KEY HIGHLIGHTS
- Cerebras Systems Inc. raised $5.5 billion in its May 2026 IPO.
- The company claims its Wafer-Scale Engine delivers 10 to 15 times faster inference than other platforms.
- Cerebras’ chip is over 50 times larger than any prior semiconductor, designed to keep compute and memory closely integrated.
- Agentic workflows, which rely on simultaneous coordination of multiple AI agents, require high-speed inference.
- Enterprises are shifting focus from 'token maxing' to maximizing value per token in AI applications.
Cerebras’ $5.5B IPO and hardware focus
According to SiliconANGLE, Cerebras Systems Inc. raised $5.5 billion in its May 2026 initial public offering, reflecting strong investor confidence in its AI-focused chip technology. The company, which went public earlier this year, has built its business around delivering faster processors for AI workloads.
Why inference speed matters for agentic AI
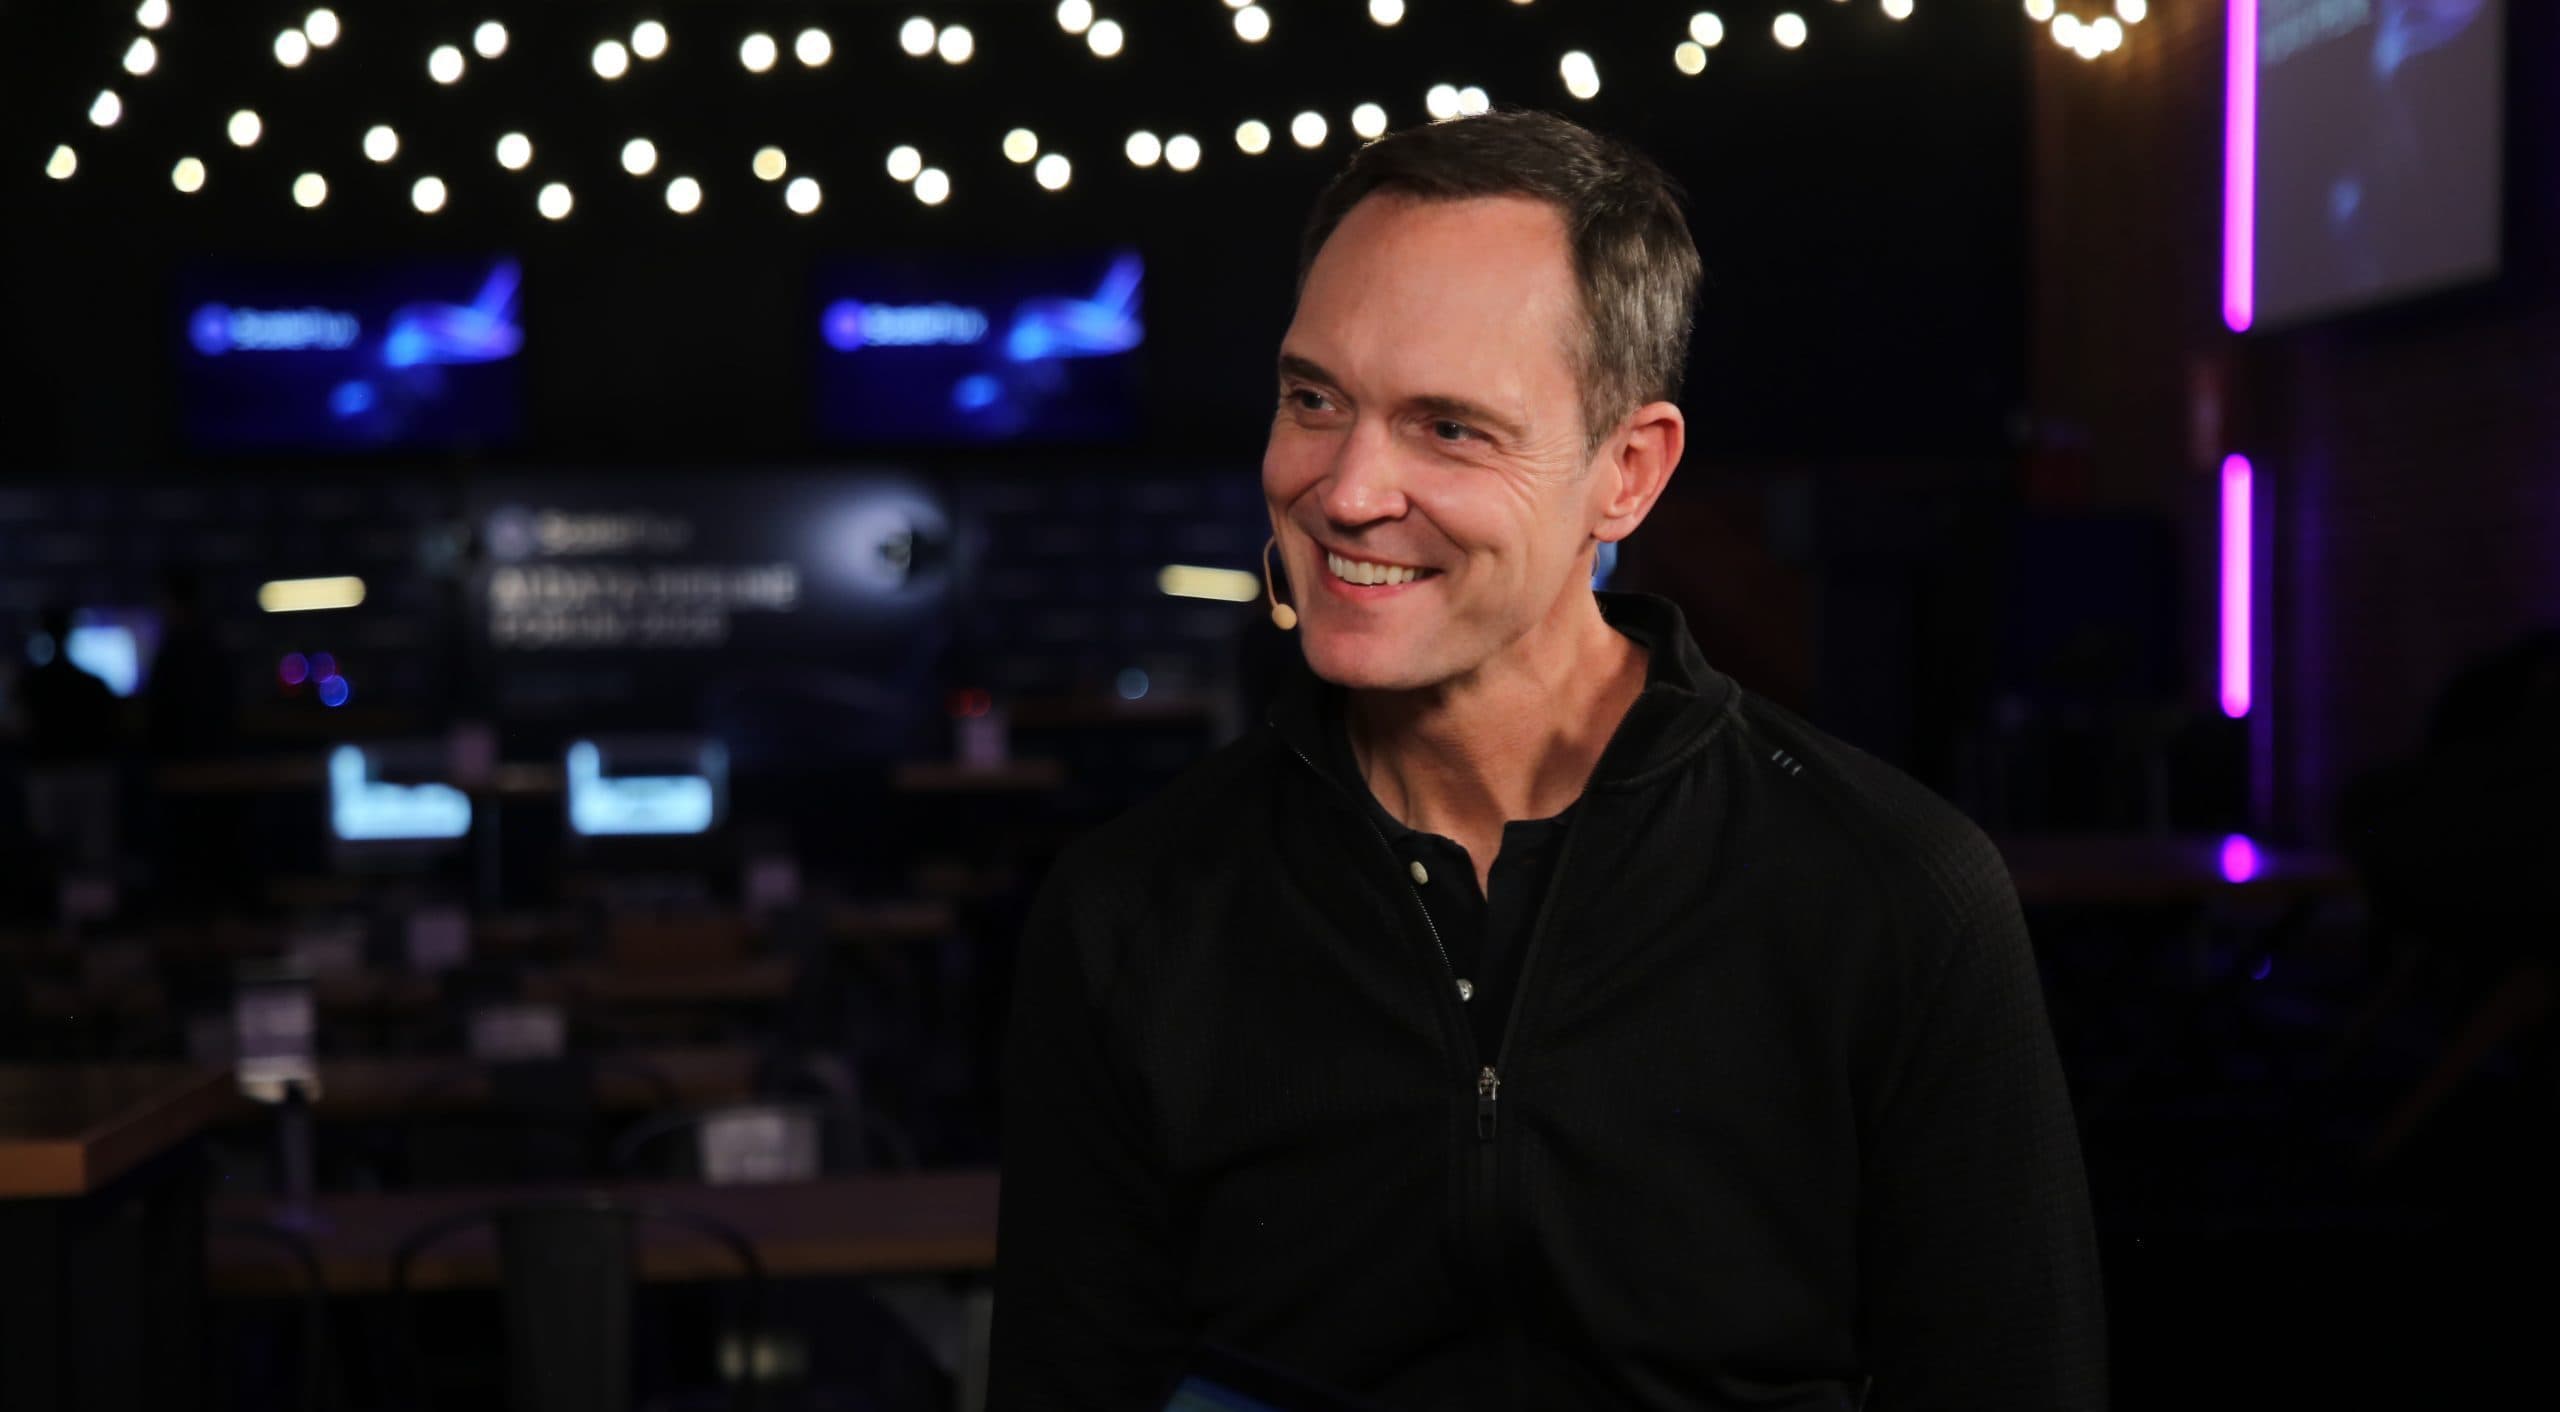
During the AI Data Pipeline Forum, Cerebras executives emphasized the importance of inference speed for agentic workflows. The company’s Chief Strategy Officer, Andy Hock, reportedly stated that AI applications require not just substantial compute power, but also proximity between compute and memory to optimize performance.
Cerebras claims its Wafer-Scale Engine—a chip over 50 times larger than any previous semiconductor—addresses this need. According to SiliconANGLE, the company asserts that its hardware delivers inference speeds 10 to 15 times faster than competing platforms.
Enterprises prioritize value per token
John Furrier and Dave Vellante, co-founders of SiliconANGLE Media and theCUBE Research, reported that enterprises are moving away from what they termed 'token maxing'—prioritizing sheer token volume—and toward extracting more value from each token generated by AI models.
This shift aligns with the demands of agentic workflows, where multiple AI agents collaborate in real time to complete tasks. Faster inference speeds, Cerebras argues, are essential to support this coordination without latency bottlenecks.
Background on Cerebras’ technology
Cerebras Systems Inc. first gained attention for its unconventional chip design, which integrates an entire silicon wafer into a single processor. This approach eliminates the need for multiple interconnected chips, reducing latency and improving performance for AI workloads.
The company’s May 2026 IPO and subsequent financial results, reported in June 2026, suggest growing market interest in specialized AI hardware.
What this means
Lazyfounder analysis — our interpretation, not reported fact.
Cerebras’ messaging underscores a growing recognition in the AI industry: raw compute power alone isn’t enough. Founders building agentic workflows—where multiple AI models collaborate to solve complex tasks—must prioritize inference speed and efficiency. This shift could favor specialized hardware providers like Cerebras, particularly as enterprises move beyond merely scaling token usage to optimizing the value extracted from each token.
For operators, this signals a need to evaluate infrastructure not just on cost or scalability, but on how well it supports real-time, high-throughput AI interactions. The emphasis on speed may also accelerate adoption of purpose-built chips over general-purpose GPUs, especially in latency-sensitive applications.
Key takeaways
- Agentic workflows demand faster inference speeds, making hardware performance a critical factor for AI applications.
- Cerebras’ $5.5 billion IPO and claims of 10-15x faster inference highlight the competitive edge of specialized AI processors.
- Enterprises are prioritizing value per token over sheer token volume, requiring more efficient AI infrastructure.
- Founders should assess whether their AI workloads benefit from purpose-built chips like Cerebras’ Wafer-Scale Engine, particularly for latency-sensitive use cases.
FAQ
What is Cerebras’ Wafer-Scale Engine?
The Wafer-Scale Engine is Cerebras’ flagship chip, designed to be over 50 times larger than any prior semiconductor. It integrates an entire silicon wafer into a single processor, reducing latency by keeping compute and memory closely connected.
Why does inference speed matter for agentic workflows?
Agentic workflows involve multiple AI agents working simultaneously to solve complex tasks. Faster inference ensures these agents can coordinate in real time without delays, which is critical for applications like autonomous decision-making or real-time data analysis.
How does Cerebras’ technology differ from traditional GPUs?
Unlike traditional GPUs, which rely on multiple interconnected chips, Cerebras’ Wafer-Scale Engine uses a single, large chip to minimize latency and maximize speed. The company claims this design delivers significantly faster inference for AI workloads.
Related on Lazyfounder
Sources
- SiliconANGLE · 2026-10-15
Cerebras highlights inference speed advantage in agentic workflows
This story is an original summary drafted with AI by Lazyfounder from the reporting listed above and checked by automated validation. Facts are attributed to their original publishers; sections marked as analysis are Lazyfounder's. Where a source is in another language, facts were machine-translated and quotations are reported, not reproduced. Read the original coverage via the links, and see our AI policy and corrections policy.
About the author
Editor, Lazyfounder
Tarun Mottlia edits LazyFounders, covering Indian startups, funding rounds, AI and product launches. Every story on the site is AI-assisted and checked against its cited sources before publication.
More stories by Tarun MottliaGet the LazyFounder Brief
Startup, funding and AI news in a five-minute read. Join the early-access list.
